
ASRock Intel Arc Pro B60 Creator 24GB
3.9Editor score
24GB GDDR6 memory capacity
Intel Xe2-HPG AI architecture
Linux multi-GPU scaling support
Discover the best GPU for Llm workloads in our comprehensive guide comparing top models for speed, memory, and efficiency in local AI inference.
Finding the right GPU for Llm tasks requires balancing memory capacity, bandwidth, and architectural support for AI acceleration. Modern workloads demand hardware that can handle large parameter counts without constant offloading to system RAM.
We evaluated ten top models based on architecture, VRAM size, bus width, and professional support. Our analysis focuses on real-world performance for local inference, fine-tuning, and multi-GPU scaling potential in workstation environments.
Each selection highlights key strengths and trade-offs to help you match hardware to your specific model size and budget. Prices fluctuate frequently, so verify current listings before purchasing to ensure you get the best value available today.
3.9Editor score

3.6Editor score

This side-by-side comparison highlights the key specifications and capabilities of each GPU to help you evaluate which model best fits your Llm workload requirements and budget constraints.




This ASUS Turbo Radeon AI PRO R9700 stands out with its 32GB GDDR6 memory and dedicated AI accelerators. It is engineered specifically for running local language models and fine-tuning tasks without relying on cloud resources.
We may earn a commission when you buy through this link, at no additional cost to you.
The 128 AI Accelerators deliver up to 1,531 TOPS in INT4 precision, making inference fast and efficient. Its 32GB capacity allows you to host larger parameter models locally without offloading to system RAM.
While the thermal design is robust with phase-change pads, the single blower style requires careful airflow planning in multi-GPU setups. Software support is still maturing compared to NVIDIA options.
This card is ideal for users prioritizing raw memory capacity and cost efficiency over ecosystem maturity. If you are building a local AI cluster or need high-bandwidth inference, this is a strong candidate.
Designed for dense multi-GPU builds, this card supports PCIe 5.0 scaling for distributed training and inference workloads across multiple nodes.
Phase-change thermal pads and dual ball fan bearings ensure consistent performance under heavy sustained loads typical of AI training sessions.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Arc Pro B60 offers 24GB GDDR6 memory at a competitive price point. It features the Intel Xe2-HPG architecture with 197 INT8 TOPS, making it accessible for entry-level local Llm inference.
We may earn a commission when you buy through this link, at no additional cost to you.
Its 24GB capacity handles moderate-sized models comfortably while its Linux multi-GPU support allows scaling across multiple cards for larger workloads. The 4X DP 2.1 outputs enable expansive multi-monitor workflows.
The blower-style cooling is effective for dense builds but can be noisy under load. Software drivers are improving but may lack some optimizations found in established ecosystems.
For developers building cost-effective local AI setups, this card provides a solid balance of memory and compute. It is an excellent entry point for experimentation and light production work.
The 24GB GDDR6 offers significant memory headroom for inference without the premium price tag of enterprise-grade solutions.
Optimized for Linux multi-GPU deployments, this card enables you to scale performance across multiple GPUs efficiently.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVIDIA RTX PRO 6000 Blackwell delivers unmatched capacity with 96GB of GDDR7 ECC memory. It is engineered for agentic workflows and advanced data science where VRAM bottlenecks must be eliminated entirely.
We may earn a commission when you buy through this link, at no additional cost to you.
Its Blackwell architecture delivers up to 3,511 TOPS of AI performance while maintaining a modest 300W power draw. The 512-bit bus width ensures maximum bandwidth for handling massive deep learning datasets.
The Max-Q design fits standard desktops with excellent thermal management, enabling multi-GPU scaling without excessive heat. However, it is a significant investment reserved for professional workstations.
This card is essential for teams needing local hosting of massive open-source LLMs or complex multi-modal models. It provides the highest reliability and performance ceiling for demanding professional environments.
With ECC memory and a 3-year manufacturer warranty, this card ensures long-term stability for mission-critical AI pipelines.
96GB of VRAM eliminates offloading, allowing full model residency for fast inference and fine-tuning without latency penalties.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE RTX 5080 Gaming OC leverages the NVIDIA Blackwell architecture and 16GB GDDR7 memory for exceptional compute performance. It includes WINDFORCE cooling and DLSS 4 support for efficient high-load tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
With PCIe 5.0 support and a powerful architecture, this card offers excellent inference speeds for models fitting within 16GB. The ecosystem ensures broad compatibility with current AI frameworks.
The primary limitation is the 16GB VRAM which may restrict larger models from running fully locally. However, its raw speed makes it suitable for quantized inference and fine-tuning smaller variants.
This card is ideal for users who prioritize speed and ecosystem compatibility over maximum VRAM capacity. It is a powerful choice for developers working with efficient model architectures.
Built on NVIDIA Blackwell, this card delivers next-gen performance and energy efficiency for complex AI workloads.
The WINDFORCE cooling system ensures stable clocks during extended inference sessions without thermal throttling.
We may earn a commission when you buy through this link, at no additional cost to you.
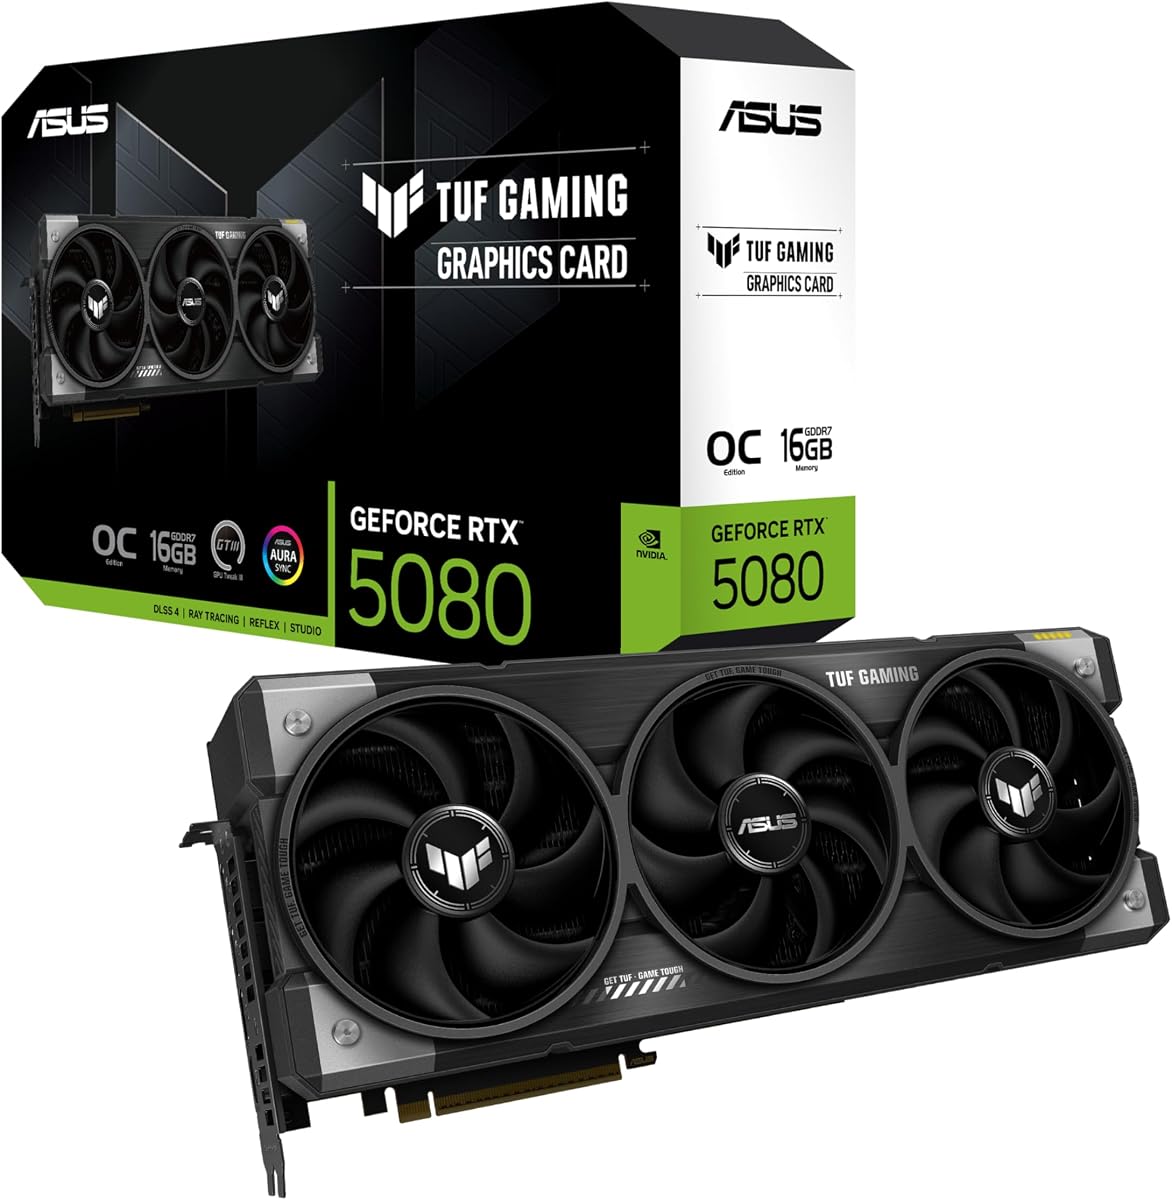
The ASUS TUF RTX 5080 prioritizes durability with military-grade components and phase-change thermal pads. It is powered by NVIDIA Blackwell and delivers solid 16GB GDDR7 performance for AI tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
Its 3.6-slot design maximizes airflow while the Auto-Extreme manufacturing ensures higher reliability. This card is built to sustain heavy loads over long periods without degradation.
While the 16GB VRAM is a constraint for very large models, the thermal design allows sustained performance without throttling. The OC mode provides additional headroom for optimized workloads.
Choose this card if you need maximum reliability and thermal stability for continuous operation. It is a robust choice for developers working in demanding workstation environments.
Phase-change thermal pads outlast traditional paste, ensuring consistent performance under sustained GPU loads.
Built with military-grade components to deliver rock-solid power and longer lifespan for ultimate durability.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Radeon AI PRO R9700 Creator is engineered for professional workloads with 32GB GDDR6 memory. It features AMD RDNA 4 with dedicated 2nd Gen AI Accelerators for groundbreaking compute performance.
We may earn a commission when you buy through this link, at no additional cost to you.
Its vapor chamber heatsink and industrial thermal interface material ensure reliable cooling under sustained professional loads. The 2-slot design maximizes density in server racks and multi-GPU builds.
While it offers professional drivers and ISV certification, the blower style cooling may be louder than consumer models. It prioritizes stability and compatibility with enterprise software.
This card is best suited for studios and developers requiring certified professional hardware. It balances high memory capacity with reliability for long-term professional deployment.
ISV Certified drivers and professional validation ensure stability for engineering and design software.
Vapor chamber heatsink with Honeywell PTM7950 material ensures reliable cooling under professional loads.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE Radeon RX 9070 XT offers strong raw performance with 16GB GDDR6 memory. It utilizes PCIe 5.0 for fast data transfer and features WINDFORCE cooling with Hawk fans.
We may earn a commission when you buy through this link, at no additional cost to you.
Its server-grade thermal conductive gel ensures efficient heat dissipation under sustained loads. This card provides a solid balance of performance and value for entry-level AI work.
While it lacks dedicated AI accelerators found in PRO series, its raw compute is sufficient for quantized inference. The gaming-focused design may not suit all enterprise environments.
This card is ideal for users seeking strong performance without professional premium pricing. It works well for local testing and smaller model deployments.
PCIe 5.0 support provides double the bandwidth of PCIe 4.0 for faster data transfer.
Server-grade thermal conductive gel and Hawk fans ensure efficient cooling during intensive tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Dual RTX 5060 Ti packs 16GB GDDR7 memory into a compact 2.5-slot design. It features NVIDIA Blackwell architecture with 767 AI TOPS for efficient inference in smaller chassis.
We may earn a commission when you buy through this link, at no additional cost to you.
Its Axial-tech fan design and 0dB technology ensure quiet operation during light loads. The Dual BIOS allows toggling between Quiet and Performance profiles for flexibility.
While the compute density is lower than flagship cards, its efficiency makes it ideal for desktop workstations. It balances performance with low power consumption.
This card is best for users needing quiet operation and space efficiency. It is a solid choice for local inference on smaller models.
The 2.5-slot design maximizes compatibility and cooling efficiency for superior performance in small chassis.
0dB technology lets you enjoy light gaming and inference in relative silence when under low loads.
We may earn a commission when you buy through this link, at no additional cost to you.
The Tesla L40S provides 48GB memory capacity specifically for AI HPC workloads. It features an enterprise-grade build with specialized cooling for server environments.
We may earn a commission when you buy through this link, at no additional cost to you.
While consumer interfaces are absent, the raw compute and memory capacity make it ideal for data center deployment. It supports high-density multi-GPU configurations.
This card is designed for rackmount systems where passive cooling is viable. It offers excellent reliability but requires specific infrastructure support.
Choose this card for data center deployments needing high memory density. It is a robust solution for production inference clusters.
Designed for data center environments with robust build quality and specialized cooling solutions.
Built specifically for high-performance computing and AI workloads in professional environments.
We may earn a commission when you buy through this link, at no additional cost to you.
This NVIDIA RTX PRO 6000 OEM version offers 96GB DDR7 ECC memory and 5th Gen Tensor Cores for unparalleled compute. It is designed for AI, design, simulation, and engineering workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
PCIe Gen 5 support doubles bandwidth compared to Gen 4 ensuring rapid data transfer. The ECC memory ensures data integrity for critical scientific and enterprise tasks.
While retail packaging is absent, the performance and reliability are unmatched. It is suitable for labs and enterprises needing maximum local compute power.
This is the ultimate choice for research labs hosting massive models locally. It provides the highest tier of performance and stability available.
5th Gen Tensor Cores deliver up to 3X the performance of the previous generation for faster AI processing.
PCIe Gen 5 support provides double the bandwidth of PCIe Gen 4 for faster data-transfer speeds from CPU memory.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right GPU for Llm tasks requires evaluating memory capacity, architecture support, and ecosystem compatibility to ensure efficient local inference and fine-tuning.
VRAM capacity determines the maximum model size you can load locally without offloading to system RAM. For modern LLMs, 24GB or higher is recommended for full model hosting, while 16GB may suffice for quantized versions.
Aim for at least 24GB VRAM to ensure flexibility and future-proofing for larger model architectures.
Memory bandwidth affects how fast the GPU can access data during inference. Higher bandwidth reduces latency and improves throughput, especially for large context windows.
Prioritize GPUs with high bandwidth like GDDR7 or wide bus widths for optimal performance.
Dedicated AI accelerators like Tensor Cores or XMX engines significantly boost inference speed and efficiency. These units are optimized for matrix operations common in transformer models.
Choose models with dedicated AI engines for faster and more efficient local inference.
Modern architectures like Blackwell or RDNA 4 offer better efficiency and newer instruction sets for AI tasks. Ensure the architecture supports the latest AI frameworks.
Selecting the latest architecture ensures compatibility with current tools and optimized performance.
The availability of drivers and framework support is crucial for ease of deployment. NVIDIA CUDA is widely supported but other platforms are improving rapidly.
Verify that your preferred AI frameworks are fully compatible with the GPU manufacturer's software stack.
Power requirements impact cooling needs and overall system efficiency. Enterprise models often offer better performance per watt for sustained workloads.
Evaluate your power supply capacity and cooling infrastructure before purchase to ensure stability.
Scaling across multiple GPUs allows you to distribute massive models. PCIe 5.0 and specialized interconnects enhance this capability for clusters.
Look for cards explicitly optimized for multi-GPU scaling if you plan to build a local cluster.
Thermal solutions determine how well the card handles sustained loads without throttling. Blower style cards are denser but often louder than open-air designs.
Ensure your case supports the chosen thermal design to maintain peak performance during long training sessions.
Start by ensuring your power supply meets the wattage requirements of your GPU. Modern AI cards often demand robust PSUs with adequate PCIe power connectors.
Install the latest drivers and verify compatibility with your AI framework. Proper driver installation ensures stable inference and maximizes hardware utilization.
Monitor thermal performance using vendor tools and keep airflow unobstructed. Regularly cleaning dust filters helps maintain cooling efficiency during heavy workloads.
For most modern LLMs, at least 24GB VRAM is recommended to host models without offloading. Smaller quantized models may run on 16GB but performance and model size will be limited.
NVIDIA Blackwell and AMD RDNA 4 architectures are currently top choices for AI acceleration due to dedicated AI accelerators and high memory bandwidth optimized for transformer workloads.
Yes consumer GPUs are widely used for production but enterprise models offer better reliability ECC memory and support for continuous high-load workloads in professional environments.
High memory bandwidth reduces latency during token generation by allowing faster data access. This is critical for real-time inference and maintaining high throughput with large models.
Sustained AI workloads generate significant heat so proper cooling is essential. Blower style fans are ideal for dense builds while open-air designs work for standard chassis.
PCIe 5.0 provides double the bandwidth of PCIe 4.0 which helps with faster data transfer between CPU and GPU. It is beneficial but not strictly necessary for most local inference tasks.
Choosing the right GPU for Llm depends heavily on your model size and budget. The ASUS Turbo Radeon AI PRO R9700 and NVIDIA RTX PRO 6000 lead in memory and performance respectively.
Prioritize VRAM capacity and dedicated AI accelerators to ensure efficient local inference. Balancing memory and speed will give you the best return on investment.
Always verify current availability and prices before purchasing. Technology evolves quickly so checking the latest listings ensures you secure the best value for your needs.